
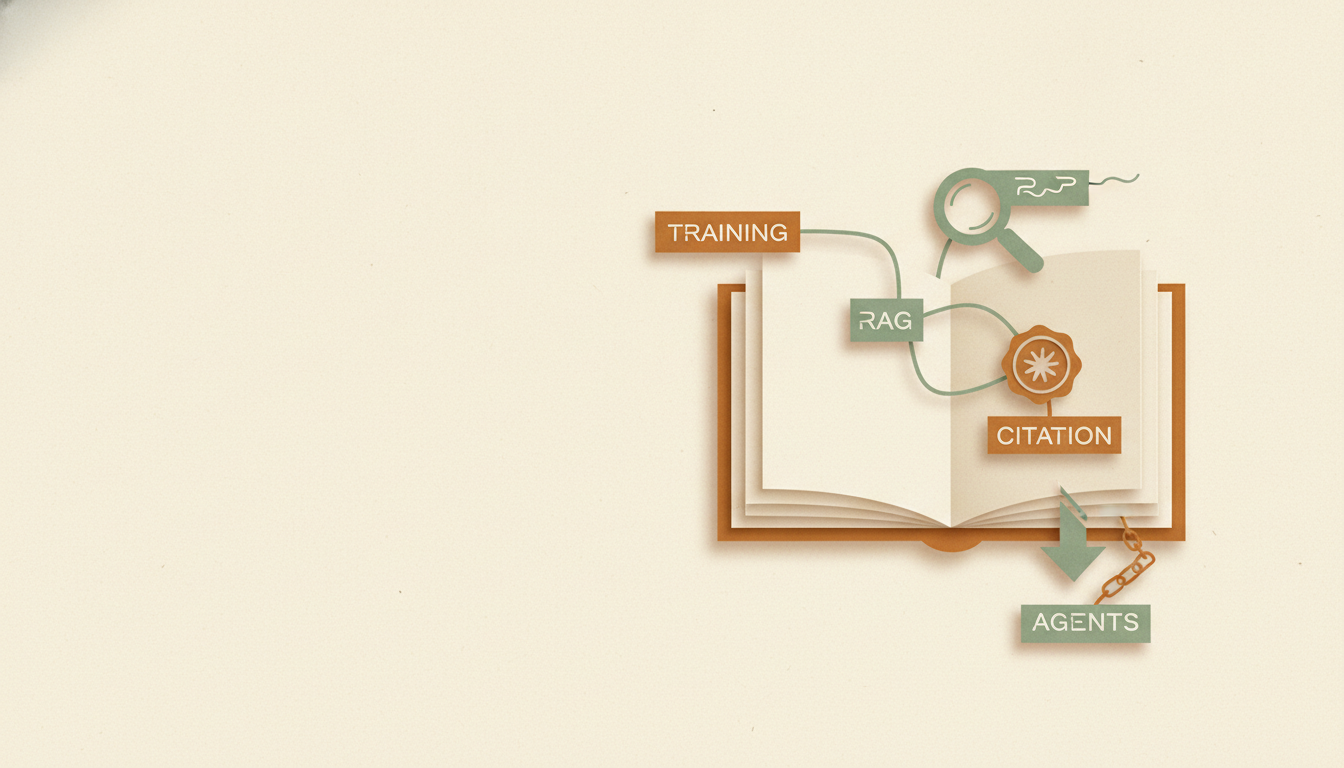
A publisher asked to "license content for AI" is usually being asked to grant several different things at once. Training changes a model once. Retrieval puts a passage into an answer every time someone asks. An agent fetches a page on demand, for a task the publisher never sees.
Each of those uses calls for a different right, produces a different record and supports a different price. A single fee for "AI use" averages them, and the average tends to favour the party that can count.
In short
An AI content license should be split by use, not signed as one block. Five uses matter: training (general-purpose or fine-tuning), indexing, retrieval-augmented generation (RAG) and grounding, citation and display, and agent access.
Three machine-readable vocabularies already separate training from use as model input: RSL 1.0, the IETF AI Preferences draft and Cloudflare's Content Signals. None of them treats citation as a use of its own, and none has a category for agents. Citation is a condition attached to a use; an agent is a way of delivering model input.
The working rule follows. For each use, name the right, the record the publisher will receive and the payment model that record can support. A use that produces no record the publisher can check cannot carry a usage-based price.
The standards already split training from input
RSL 1.0, published as a recommendation on 10 December 2025, defines ai-train (training or fine-tuning), ai-input (content used as model input, including RAG, grounding and AI search summaries) and ai-index (inclusion in an AI system's internal index or retrieval database). It also lists payment types: one-time purchase, subscription, payment per training use, per crawl, per contribution to an AI output, and attribution.
The IETF AI Preferences working group draws the same line. Its vocabulary draft of 14 September 2026 separates train-ai, which modifies a generative model's parameters, from ai-use, where the asset serves as input to the model; its authors state that the text does not yet reflect working-group consensus. Cloudflare's Content Signals, introduced in September 2025 for more than 3.8 million domains using its managed robots.txt, apply the same split: search, ai-input and ai-train.
Regulation is moving the same way. The UK Competition and Markets Authority's conduct requirement on Google search, announced in June 2026, gives publishers control over fine-tuning separately from grounding in AI features. When the signalling layer, a standards body and a regulator all separate training from input, a contract that bundles them gives away a distinction the publisher could have priced.
This is a different question from the one the Ross case raised. Sorting AI uses by economic function — improving a licensed product or building a substitute for it — decides whether a use should be licensed at all. The matrix below answers the next question: once a use is licensed, which record proves it and which payment that record can support.
The licensing matrix: use, right, record, payment
Use | What happens to the content | Right to define | Record to require | Payment model it supports |
|---|---|---|---|---|
General-purpose training | Changes a broad model's parameters once per model version; deleting the copy does not undo it | Corpus scope, model versions covered, downstream uses, competing products, deletion of training copies | Manifest of works per model version, training date, model identifier, deletion attestation | One-time or per-corpus fee, repriced at each new model version |
Fine-tuning for a named product | Specialises a base model for one domain or function | Base model, domain, permitted function and customers, retraining | Works and versions used, fine-tuning run, resulting model, declared purpose | Fee per project or per resulting model |
Indexing | Stores copies in a retrieval database for later use | Retention period, refresh frequency, editions covered, deletion at expiry | Index inventory by work and version; proof of deletion at termination | Access or subscription fee |
RAG and grounding | Retrieves passages into the model's context for each query | Retrieval scope, excerpt length, verbatim display, caching | Per work: passages made available to the model and passages included in the final answer; query context | Per-use payment or usage-weighted pool |
Citation and display | Shows the source, an excerpt or a link to the user | Attribution format, functional link, prominence, excerpt limits | Attribution rate on sampled answers; link impressions and clicks | Modifier on the other rows, or a fee per attributed display |
Agent access | Fetches content on demand to complete a task for a user | Agent and principal identity, delegated authority and budget, permitted actions, task scope, no retention | Agent and principal identifiers, offer accepted, content accessed, action taken, cost | Per-request or per-crawl payment |
Read the matrix by column. The record column decides what the payment column can be.
Training produces a manifest, not a meter. Once a model is trained, no reliable per-answer measure of one work's contribution exists today, so training is priced as a corpus and repriced when a new model version is trained on it. Courts now treat that corpus as a market of its own: affirming on 29 September 2026 that training Ross's tool on Westlaw headnotes was not fair use, the Third Circuit observed that "the market for licensing headnotes as text to train AI is rapidly developing." The repricing logic is the mechanism behind the gap between one-time and recurring AI licensing revenue.
RAG is the opposite: every retrieval is an event. That is why usage-based offers target the input side, such as the Pay Per Use model Cloudflare announced on 1 July 2026. COUNTER's best practice on AI usage metrics, updated on 30 June 2026, draws the line that matters for price. It counts AI requests, when a model could access a passage's full text, separately from AI investigations, when a passage was selected for the final answer. Only the second is a contribution. The same guidance states that AI reporting is not subject to COUNTER's formal audit, which is why the record column must name who produces the count — the question at the centre of who audits the usage number in AI licensing deals.
Indexing is the row most contracts forget. A retrieval database holds copies between queries; without a retention and deletion clause, a RAG license can outlive its own term.
Citation is a condition, not a use
Citation is often negotiated as if it were a separate right. RSL treats attribution as a payment type — visible credit plus a functional link — rather than a usage category, and neither the IETF draft nor Content Signals gives it a category of its own.
That is the correct reading for a license. A citation qualifies a retrieval or a display; it does not replace payment for it, and it does not cure a use the license never granted. In practice, attribution works best as a rate modifier: a lower per-use rate with guaranteed attribution, a higher one without.
The modifier only works if it is measured. A passage can shape an answer without being credited, which is why retrieved is not cited, and why the record column asks for an attribution rate rather than a promise.
Agents are a delivery mode, priced per request
None of the three vocabularies defines a separate category for agents. An agent that fetches an article to answer a question is using the content as model input. An agent that fetches it to compare prices or complete a booking may generate nothing at all.
The licensing difference is therefore the access pattern, not the use type: on demand, task-scoped, often without retention. Cloudflare's July 2026 announcement named You.com as an early partner whose agent pays on demand for a specific piece of premium content.
That model works only if the agent identifies itself, and only within the authority and budget its principal delegated. COUNTER already provides an optional "Agent" access method for reporting. An anonymous fetch can be neither billed nor audited, so the first right to define is agent and principal identity, and the first record to keep is the publisher's own log of crawler identity and declared purpose.
The objection: "Unbundling makes deals impossible to sign"
Buyers prefer one fee for all AI use, and early in a market a simple deal can be worth more than a precise one. The objection is fair.
But the matrix does not require one price per use. It requires one line per use in the scope clause and one record per line. A blanket fee can stay, provided the contract states which uses it covers, which it excludes, and which records will allow it to be repriced at renewal.
Without that, the first deal becomes the market's benchmark by default, priced on the buyer's count.
What to put in the next license
First, list the uses the licensee actually plans, in RSL or IETF terms, so the contract and the publisher's machine-readable signals say the same thing.
Second, for each use granted, name the record the publisher will receive, in which format, and who produces it.
Third, match the payment model to the record: corpus fees where only a manifest exists, per-use payment where events exist, attribution as a modifier. Whatever the structure, the total still has to clear the break-even threshold calculated before negotiation.
The record column is where Citations Logic works: AI usage evidence that ties each use to a work, a right and a commercial term.
Book an AI licensing evidence review
Where to go next
For internal use inside institutions, see how CCC's higher education license separates AI reuse permission from usage signals.
For value created inside the answer interface itself, see why AI display deals need their own usage meter.
Sources
RSL Collective — Really Simple Licensing (RSL) 1.0 Specification, 10 December 2025
RSL 1.0 Specification
IETF AI Preferences working group — A Vocabulary For Expressing AI Usage Preferences, draft-ietf-aipref-vocab-08, 14 September 2026
draft-ietf-aipref-vocab-08
Cloudflare — Giving users choice with Cloudflare's new Content Signals Policy, 24 September 2025
Content Signals Policy
Cloudflare — Your site, your rules: new AI traffic options for all customers, 1 July 2026
New AI traffic options for all customers
COUNTER Metrics — Best Practice on Generative and Agentic AI Usage Metrics, updated 30 June 2026
Best Practice on Generative and Agentic AI Usage Metrics
Mitchell Silberberg & Knupp — Third Circuit: Training an AI Tool on Westlaw Headnotes to Compete with Westlaw Is Not Fair Use (Thomson Reuters v. Ross, No. 25-2153, 3d Cir. 29 September 2026)
Third Circuit ruling in Thomson Reuters v. Ross
Competition and Markets Authority — CMA secures fairer deal for publishers and improves Google search services in UK, 3 June 2026
CMA conduct requirement on Google search
This article is operational analysis for publishing and rights teams, not legal advice. Confirm license terms with counsel.